Production AI systems engineered for reliability, speed, and control.

Large language models are probabilistic; production software cannot be. EchoPod architects full-stack AI applications, durable workflows, and evaluation harnesses on your cloud, servers, or edge hardware.

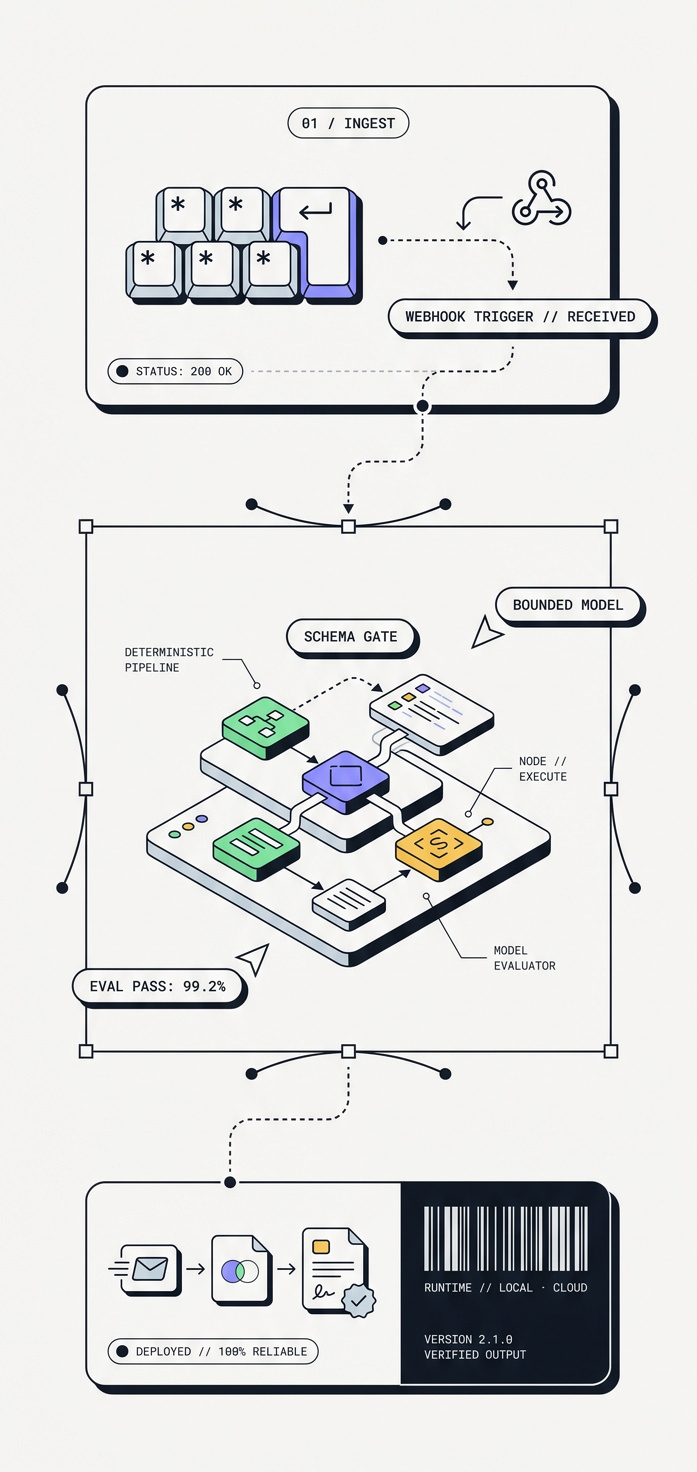
Illustration of a production AI loop: webhook ingest, bounded model execution with schema and evaluation gates, and verified local or cloud deployment.
Sprint
2–4 weeks to a testable build
Runtime
Your cloud, on-prem, or edge
Models
Right-sized hybrids, not token bloat
Deliver
Apps, pipelines, evals, sidecars

Reference architecture

Patterns we ship in your stack.

Not a hosted API wrapper—durable orchestration, evaluation gates, and runtimes deployed where your data already lives.

From shipped enterprise work. You own credentials, data, and deployment targets.

# In your environment (not a black-box SaaS)

webhook or desktop event
  → validate (schema, policy, business rules)
  → inference (bounded step, right-sized model)
  → write-back (CRM, repo, warehouse, UI state)

durable queues · idempotent steps · auditable logs
# Gate before a checkpoint ships to production

define study + rubrics (quality, drift, policy)
  → batch runs on held-out cases
  → score + inter-rater review
  → promote, hold, or roll back

exports your team owns · no mystery benchmark host
# Same app, matched to your constraints

enterprise cloud · Azure / AWS / GCP, SSO, VPC
behind firewall · on-prem workers + your data plane
workstation · compact models + desktop sidecar sync

you own credentials, data, and deployment targets
  • Visual builders
  • Durable pipelines
  • Desktop sidecars
  • Evaluation harnesses
  • Schema enforcement
  • Guardrails
  • SSO / VPC
  • On-prem
  • Edge hardware
  • Local sync

Why EchoPod

Your team is the filter, not the printer.

Most AI initiatives stall as brittle chat wrappers that fail when confronted with real business logic, strict latency budgets, or compliance rules. EchoPod separates probabilistic inference from deterministic execution, combining right-sized models, durable background workers, and embedded interfaces that integrate cleanly into your existing stack.

What we build

Four systems. One production loop.

01 · Applications

Visual builders & AI applications

Full-stack web and desktop applications, including drag-and-drop workflow canvases, that let teams compose interfaces, bind them to custom inference APIs, generate custom execution nodes, and deploy live apps with automated CI/CD.

02 · Pipelines

Durable event-driven pipelines

Webhook-triggered orchestration engines and custom node graphs built for deterministic reliability. We take structured inputs through multi-step synthesis, validation, schema enforcement, and automated system write-backs.

03 · Desktop

Embedded desktop & edge tooling

Native desktop applications, lightweight sidecar runtimes, and adaptive API-driven interfaces that keep inference, local state sync, and user workflows in a single fast loop, without browser bloat or round-trip latency.

04 · Guardrails

Model evaluation & guardrail suites

Multi-user desktop and hosted evaluation platforms for generative and predictive checkpoints. Built with batch execution, custom rubric scoring, inter-rater agreement tracking, side-by-side analytics, and automated compliance guardrails.

Selected systems

Proof of execution.

Anonymized architectural case studies based on shipped enterprise work.

Case 01

Visual builder

The challenge

Product and engineering teams needed a way to compose, test, and ship custom AI-powered internal tools without rebuilding auth, routing, and deployment infrastructure every time.

The build

Architected a drag-and-drop visual builder that lets teams assemble UI components, bind them to inference workflows, generate custom execution nodes, and publish production applications with integrated CI/CD and webhooks.

Case 02

Evaluation suite

The challenge

Engineering and compliance teams lacked a rigorous, repeatable way to benchmark new model checkpoints for output quality, drift, and IP safety before promoting them to production.

The build

Shipped a desktop and hosted evaluation suite featuring study configuration, batch inference runs, structured rubric scoring, inter-rater agreement metrics, comparative analytics, and automated export pipelines.

Case 03

Event pipeline

The challenge

High-volume structured briefs required multi-step transformation, variant generation, and formatted package delivery without manual intervention or fragile prompt chaining.

The build

Engineered an automated, webhook-triggered pipeline that ingests structured specifications, executes deterministic generation and formatting steps, enforces validation guardrails, and writes production outputs directly back to the source repository.

Architecture

Built for speed, security and zero runaway token costs.

We match the model size and runtime environment to the actual problem, avoiding frontier-model bloat where compact, specialized architectures perform faster and cheaper.

Cloud

Enterprise cloud

SSO · VPC

Containerized deployment on Azure, AWS, or GCP with full SSO authentication, VPC isolation, and multi-provider inference routing.

Firewall

Internal & on-prem servers

No leakage

Self-hosted architectures engineered to run entirely behind your firewall with zero external data leakage.

Edge

100% local & edge hardware

Zero API fees

Compact models and native desktop sidecars with local database sync that run on workstation hardware with zero recurring API fees.

How we work

Engagement models.

01

Rapid 0-to-1 architecture sprints

2-4 weeks

Turn an internal bottleneck, technical pitch, or product concept into a working, testable software system, with clear architectural boundaries on what belongs in core application code versus custom workflow nodes.

02

Custom production builds

Fixed scope

End-to-end engineering of bespoke AI applications, evaluation platforms, or durable orchestration pipelines delivered with clean documentation and handoff to your engineering team.

03

Fractional principal AI engineering

Retainer

Embedded technical leadership to guide your team on model selection, evaluation harnesses, local/cloud runtime architecture, and deterministic workflow design.

Ready to turn AI prototypes into production infrastructure?

Whether you are productizing an internal workflow, standing up model evaluations, or shipping a local-first AI application, let’s talk architecture.

ckruger@echopod.io